Turing, 1950: he proposed a test, 75 years later LLMs pass it, and it was not the right question
In 1950, Alan Turing replaced the question “Can machines think?” with a game: can a machine pass for a human? In 2025, a language model passed that test. And it turns out the test does not measure what an organisation needs to know.
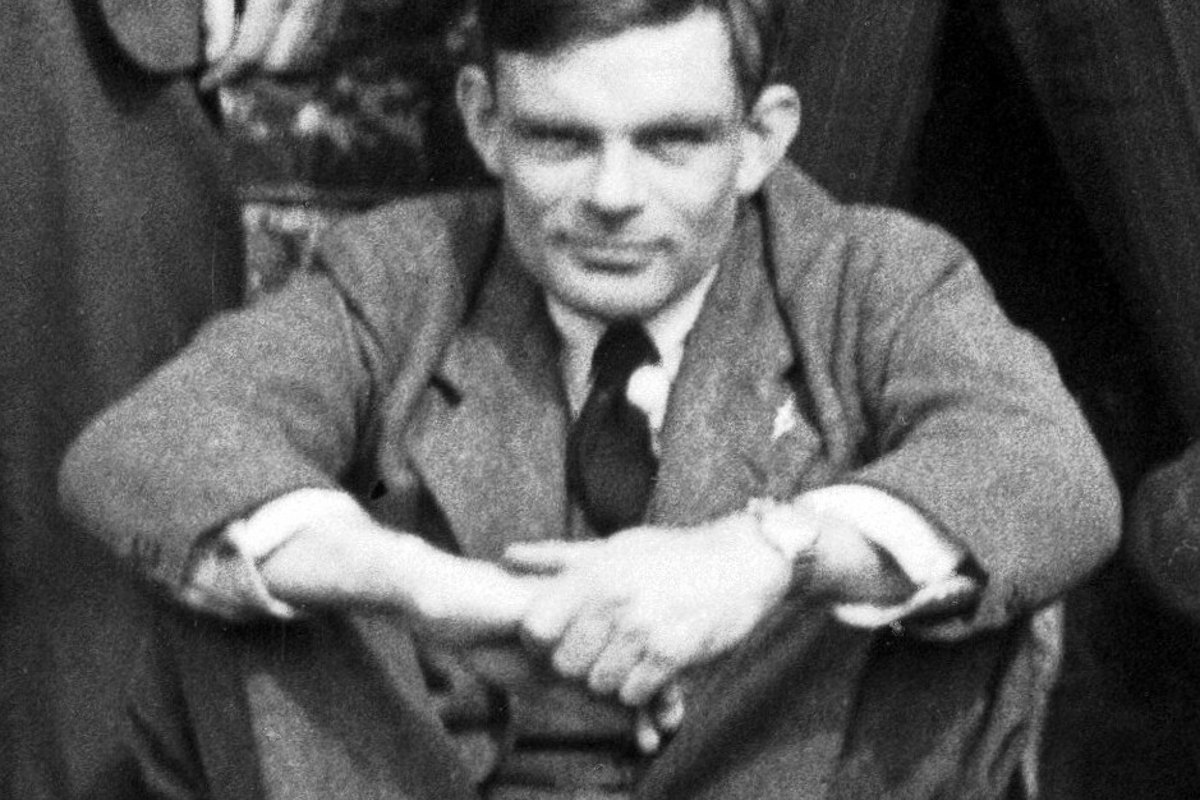
In October 1950, the philosophy journal Mind published a 28-page paper by A. M. Turing, titled “Computing Machinery and Intelligence”. Its first sentence reads: “I propose to consider the question, ‘Can machines think?’”
Seventy-five years later, a language model passed, in a controlled study, the test Turing proposed in that paper. The most useful lesson is not the one people expected. The test measures whether a machine seems human. It says nothing about what you can trust it with.
Replacing a vague question with a game
Turing does not answer his own question. He explains that if you start from the everyday meaning of “machine” and “think”, you end up looking for the answer in an opinion poll, which he calls absurd. So he replaces the question with a game he calls the imitation game.
In its original form, the game has three players: a man, a woman and an interrogator, who sits in a separate room. The interrogator asks questions in writing, ideally through a teleprinter, so that no voice gives anyone away. The interrogator must work out which is the man and which is the woman. The man tries to mislead.
Then Turing asks the real question: what happens when a machine takes the man’s place? Will the interrogator be wrong as often? These questions, he writes, replace the original one.
Later in the paper, he makes a precise prediction:
“I believe that in about fifty years’ time it will be possible to programme computers, with a storage capacity of about 10⁹, to make them play the imitation game so well that an average interrogator will not have more than 70 per cent. chance of making the right identification after five minutes of questioning.”
In other words: by around the year 2000, after five minutes of questions, an average interrogator would have no better than a 70% chance of spotting the machine. On the same page he adds that the original question, “Can machines think?”, is “too meaningless to deserve discussion”.
The detail people forget: the machine makes mistakes on purpose
To illustrate the game, Turing gives a few sample questions and answers. One of them deserves a closer look:
“Q: Add 34957 to 70764 / A: (Pause about 30 seconds and then give as answer) 105621.”
Do the sum: 34,957 plus 70,764 is 105,721, not 105,621. In Turing’s own example, the machine waits thirty seconds, like a person adding in their head, and then gives a wrong answer.
This is not a typo. A few pages later, he deals with the objection that a machine would give itself away through its accuracy at arithmetic. His reply: a machine programmed for the game “would not attempt to give the right answers to the arithmetic problems. It would deliberately introduce mistakes in a manner calculated to confuse the interrogator.”
It is all there in 1950. The test rewards imitation. A machine that wants to pass it is better off seeming human, mistakes included. The test never asks whether the answer is correct.
Turing also answers Ada Lovelace
The paper reviews nine objections to the idea of a thinking machine. The sixth is named after Ada Lovelace. In her notes on Babbage’s Analytical Engine, which Turing quotes, she wrote that “The Analytical Engine has no pretensions to originate anything. It can do whatever we know how to order it to perform.”
Turing replies with some humour: “Machines take me by surprise with great frequency.” Machines surprise him, he explains, because he does not do enough calculation to predict what they will do. The debate between the two still holds: a language model only does what its data and training allow, and yet its answers surprise the people who use it.
2025: the test is passed
In March 2025, Cameron Jones and Benjamin Bergen, cognitive scientists at the University of California San Diego, released a study titled “Large Language Models Pass the Turing Test”. The protocol follows the three-party version of the game: each interrogator chats for five minutes, at the same time, with a human and with an AI, then picks the one they believe is human.
The figures, from 284 participants and 1,023 analysed games:
- GPT-4.5, prompted to adopt a persona (a young, introverted person, familiar with internet culture, who uses slang), was judged to be the human 73% of the time. More often than the real humans it was paired with.
- LLaMa-3.1-405B, with the same prompt: 56%.
- Without the persona prompt, GPT-4.5 dropped to 36%.
- ELIZA, the 1966 program, scored 23%, and GPT-4o without a persona 21%.
The authors describe this as the first empirical evidence that an artificial system passes a standard three-party Turing test. It is a preprint, but the protocol was pre-registered and replicated on two separate populations.
What the interrogators actually tested
The most instructive part of the study is not the score. It is the analysis of what the interrogators did. In 61% of games, they made small talk: job, daily routine, activities. In half of them, they asked about emotions, opinions, humour. Knowledge and reasoning were tested in only 12% of games.
Their verdicts rested mainly on style (a typo, “more human” language) and on how smoothly the conversation flowed. Some picked a witness because it had made a mistake, which made it feel more human. Exactly the mechanism Turing described in 1950.
The result shows two things. Current models imitate human conversation very well. And what makes an AI convincing has almost nothing to do with what makes it reliable.
What this changes for an organisation
I see this confusion in many projects. An assistant gets chosen because the demo was smooth, the tone was right, the answers “looked good”. Nobody counted how many were correct.
The Turing test asks: can you tell it apart from a human? For an organisation, the useful question is different: on this specific task, with our data, at what error rate, and who fixes it when it is wrong?
In practice, before handing a task to an AI tool:
- Scope the task. One precise task with a verifiable output: classify a request, extract an amount, draft a quote.
- Build a test set. A hundred or so real cases with known correct answers, including the hard ones.
- Measure. Share of correct answers, serious errors, time saved, share of answers a human had to redo. The tool’s tone is not part of the score.
- Name a business owner. Someone who sets the acceptable thresholds and follows the numbers over time.
I describe this measurement method in more detail in an article on evaluating an AI assistant for customer support. The principle applies to any task: judge a tool on measured results, not on the impression it gives.
Turing saw it before anyone else: imitating a human and being right are two different skills. His test measures the first. Measuring the second is up to you.
Primary source: A. M. Turing, “Computing Machinery and Intelligence”, Mind, vol. 59, no. 236, October 1950, pp. 433–460.
In the same series
The other episodes of “the ancestors of LLMs”, in chronological order:
- Ada Lovelace, 1843: the engine “originates nothing”
- Markov, 1913: Pushkin letter by letter
- Shannon, 1948: a book opened at random
- Dartmouth, 1956: the first underestimated AI quote
- Rosenblatt, 1958: the Perceptron’s promise
- ELIZA, 1966: a machine that understands nothing
- Jelinek, 1980s: statistics beat grammar
- Asimov, 1991: two intelligences, not one
Frequently asked questions
What is the Turing test?
It is the “imitation game” described by Alan Turing in “Computing Machinery and Intelligence” (Mind, 1950). An interrogator exchanges written messages with two unseen parties and must work out which one is a machine. Turing predicted that by around 2000, an average interrogator would have no more than a 70% chance of getting it right after five minutes of questioning.
Has an AI really passed the Turing test?
In a pre-registered study released in March 2025 by Cameron Jones and Benjamin Bergen (UC San Diego), GPT-4.5, prompted to adopt a persona, was judged to be the human 73% of the time, more often than the real humans. Without that prompt, it dropped to 36%. The study is a preprint covering 284 participants and 1,023 games.
Why is passing the Turing test not enough to trust an AI?
The test measures whether a machine seems human, not whether it is right. Turing himself wrote that the machine would deliberately introduce mistakes to confuse the interrogator. In 2025, interrogators mostly judged style; knowledge and reasoning were tested in only 12% of games. For an organisation, a tool should be judged on measured results on its own tasks.